Local-firstcontext steering,safety gates, andpersistent memory(DAMS) for AI agents
A local-first, fine-tuned workbench (DAMS-FT) that compiles code context, warms SQLite caches, and intercepts native search tools so agents write features without re-reading the codebase.
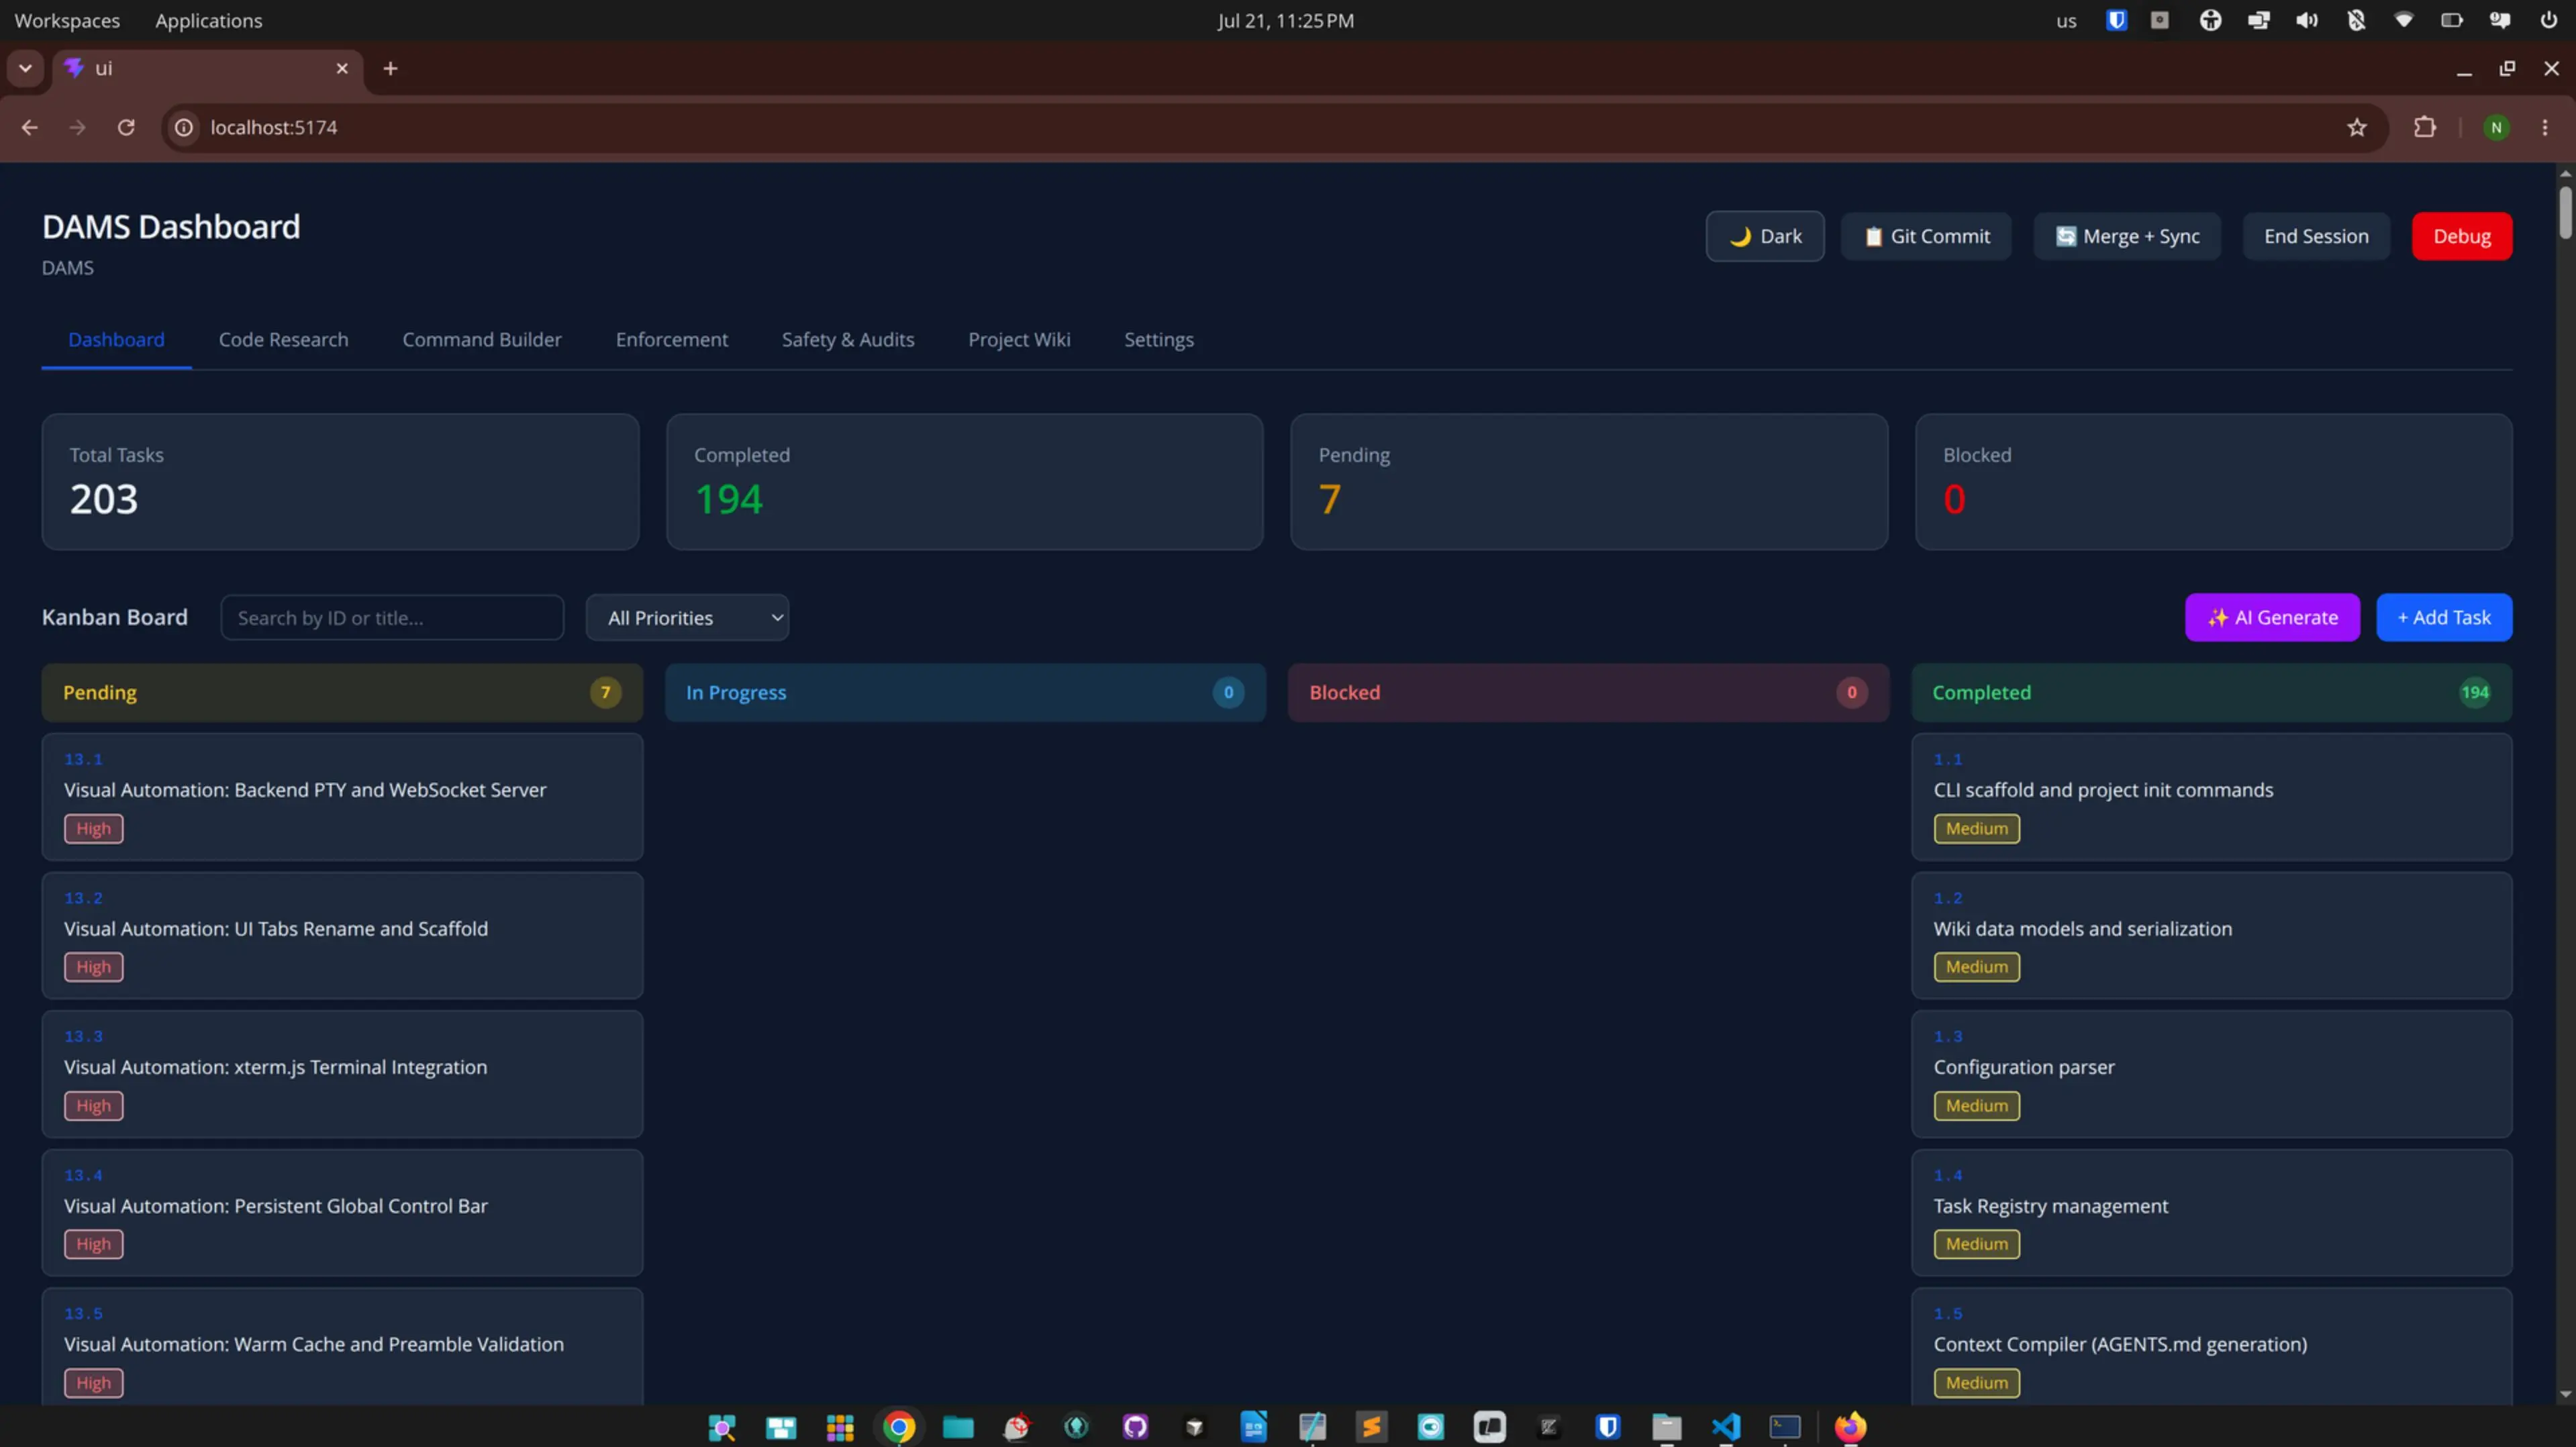
See DAMS run a feature from PRD to code
Create a project, atomize the PRD into task cards, generate queries, warm the SQLite cache, and let the agent write code from a curated scratchpad while native search stays blocked.
(4-minute walkthrough — full demo recording incoming.)
Read the demo transcript (coming soon)
The DAMS workflow
Persistent memory. Defensive by design.
From PRD to working code — every step keeps the agent focused on what matters.
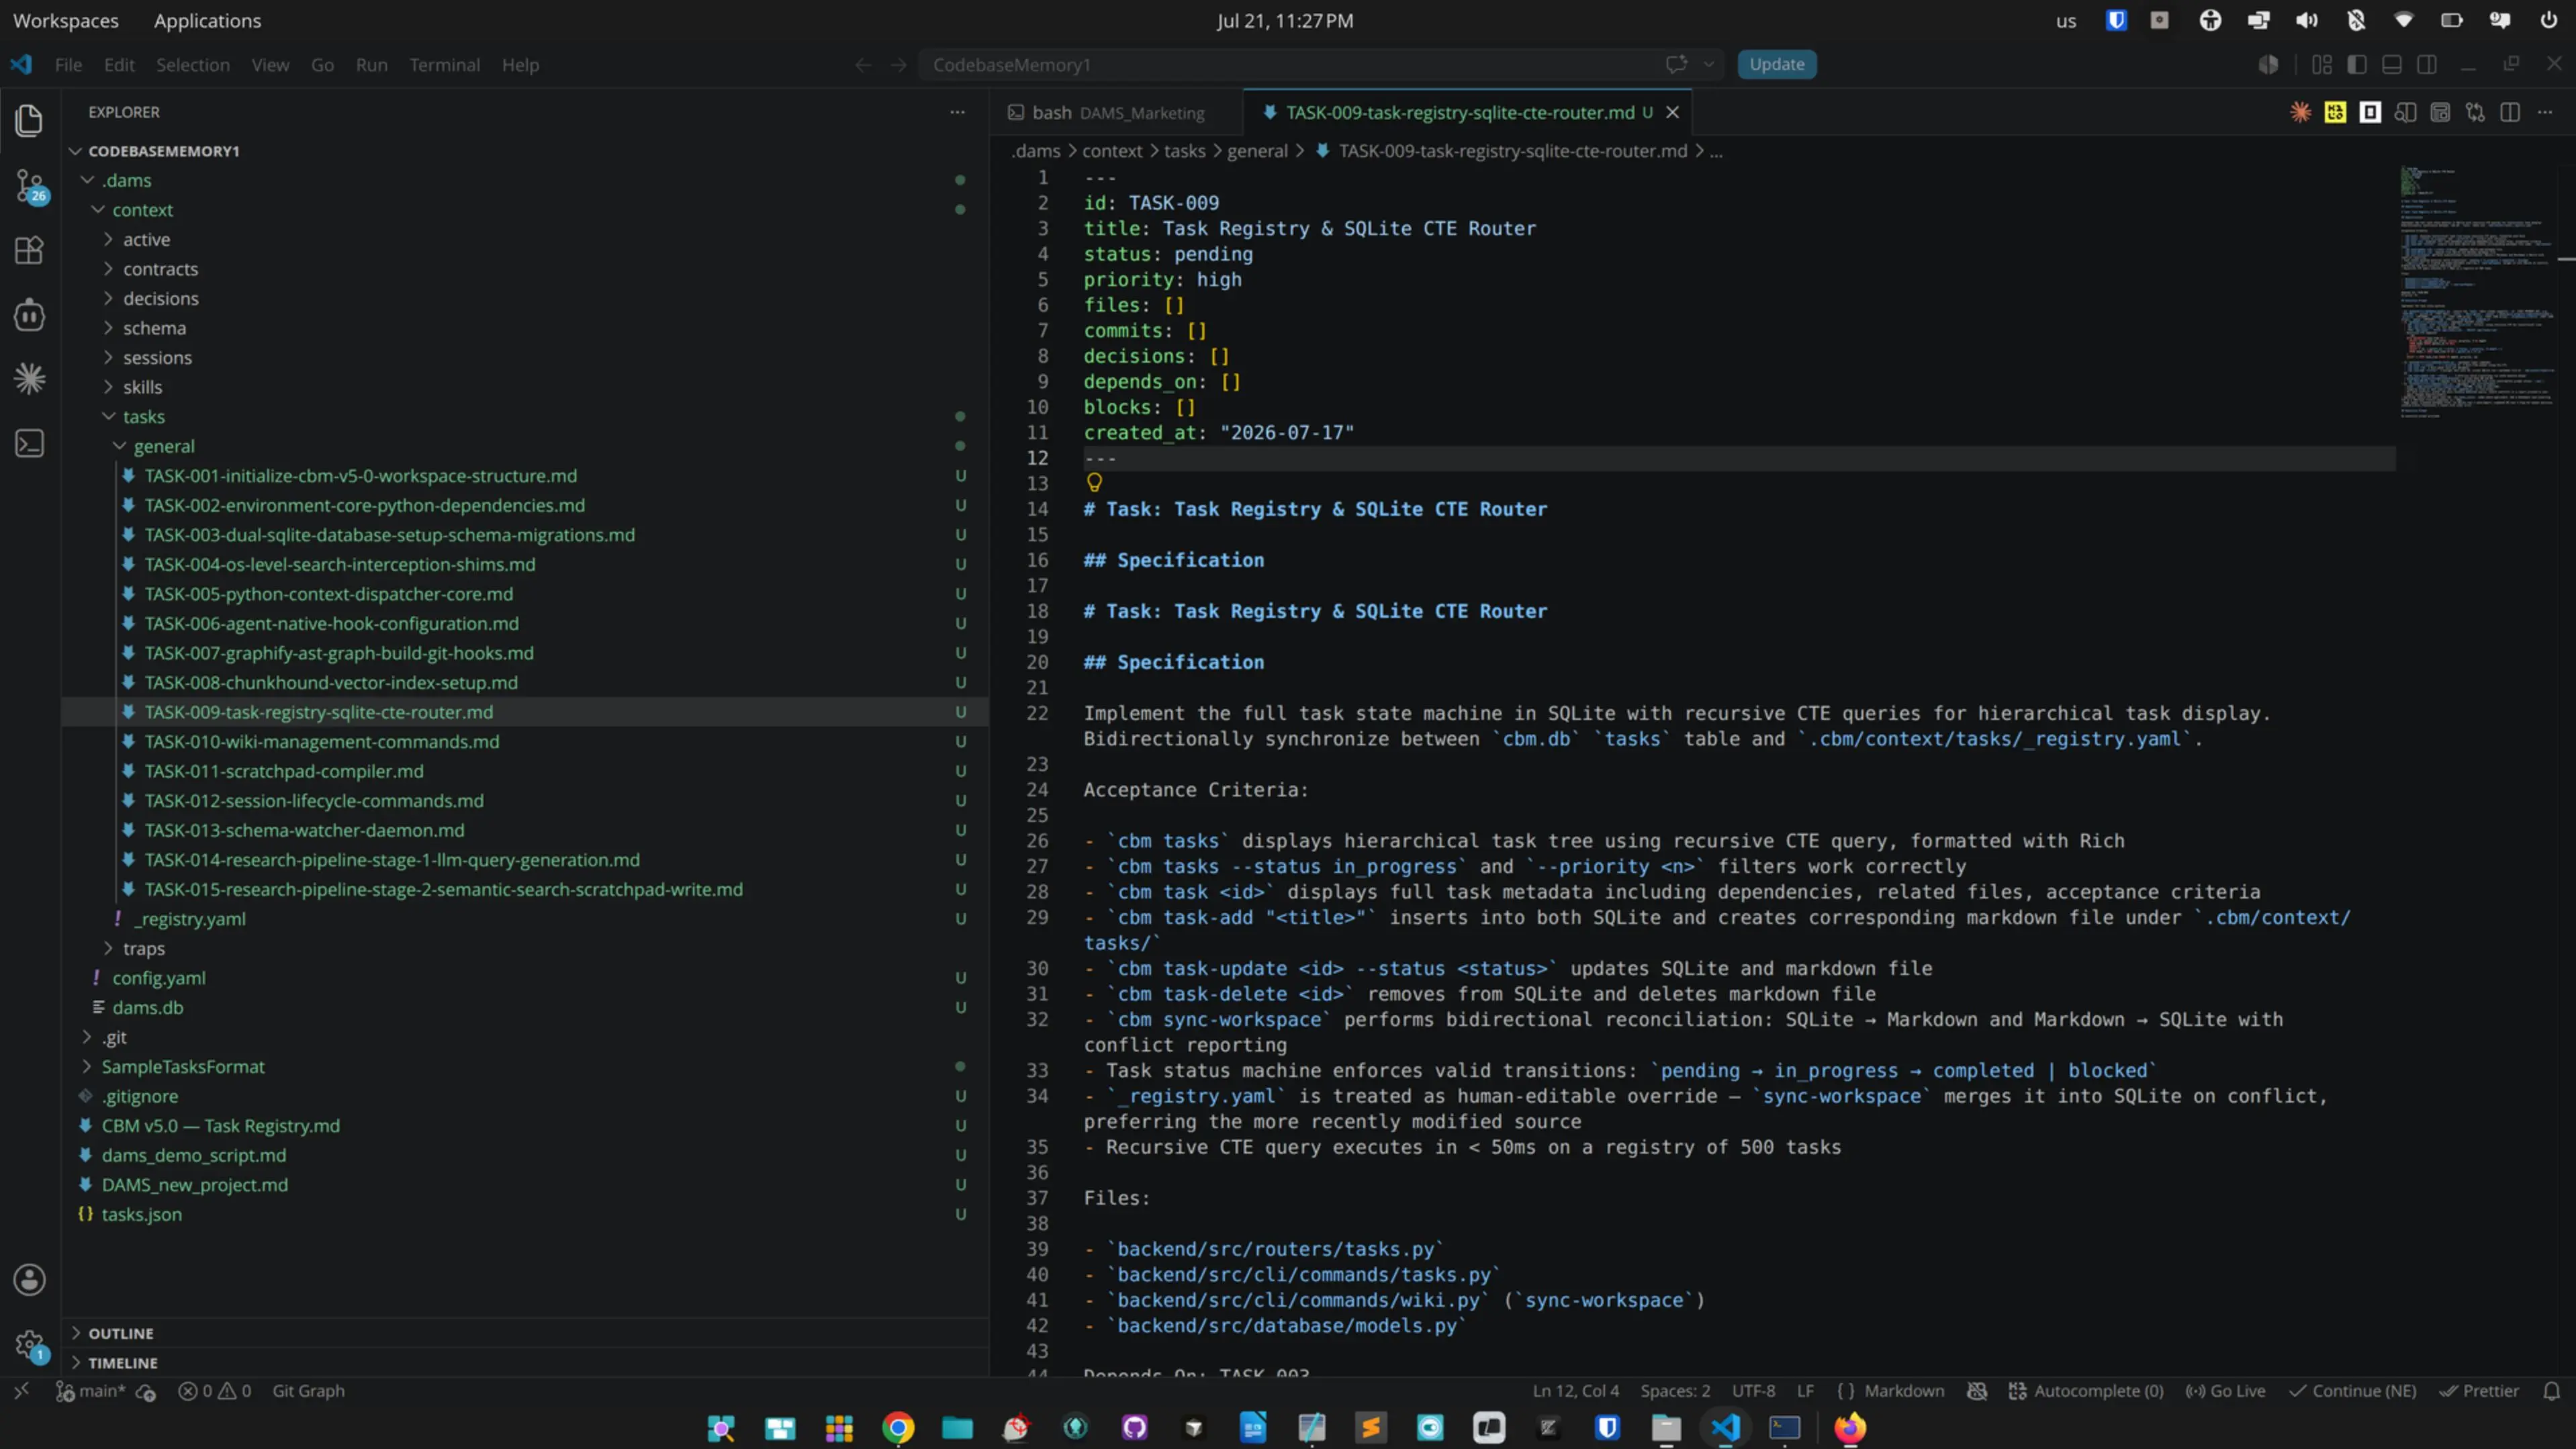
PRD Atomization
`dams atomize PRD.md` decomposes a product spec into a dependency-aware task tree tracked in `.dams/context/tasks/`.
System architecture
From PRD to code, guarded at every step.
Project Init
`dams init` / `dams new`
Initializes the workspace, setting up DAMS environment, configurations, and preparing for local-first context tracking.
Native tools route to DAMS by default. A programmatic toggle lets the agent fall back when DAMS search is not enough.
Beyond one product
Codebase Intelligence Research Lab
We study the top projects in codebase intelligence — retrieval engines, agent harnesses, knowledge graphs, observability, and local LLM tooling — and build practical, local-first products from what we learn.
DAMS ships as a container because OS-level PATH shims interfered with the host OS.
DAMS
Flagship product. PRD-to-code task automation with defensive memory and agent-native tool interception.
DAMS-Edge
Embedded-database variant for teams that need fully offline, on-device codebase intelligence.
DAMS-FT (Fine-Tuned)
Fine-tuned local LLM variant optimized for code research, query generation, and context summarization. Powered by Gortex Extension.
The DAMS-FT Local-First Model
DAMS-FT is the high-performance local model evolution of our standard DAMS RAG engine.
DAMS-FT Model
The high-performance, local model evolution of our standard DAMS RAG engine.
Deterministic Routing
Powered by Bonsai-8B to route developer prompts directly into AST code knowledge graphs.
100% Reliability
Achieves 100% tool mapping accuracy, completely eliminating model hallucination errors.
Token Compression
Uses our GCX1 wire protocol to slash LLM token overhead by 27% to 40%.
Cost-Efficient
Directly reduces external API operational inference costs and context latency.
Defensive Interception
Features an active PreToolUse Shield that intercepts and blocks raw text scans.
Speculative Security
Integrates an AST Parse Gate to validate code syntax before model inference.
Resource Friendly
Fits in a lightweight 6GB VRAM footprint for secure, local offline deployment.
Sub-300ms Speed
Delivers lightning-fast local query routing without relying on heavy cloud servers.
Enterprise Ready
The ultimate private, secure, and cost-optimized RAG engine for massive codebases.
Gortex Extension Pipeline
Explore the pipeline stages below to preview how DAMS-FT intercepts, routes, navigates, and compresses context for codebase intelligence tasks.
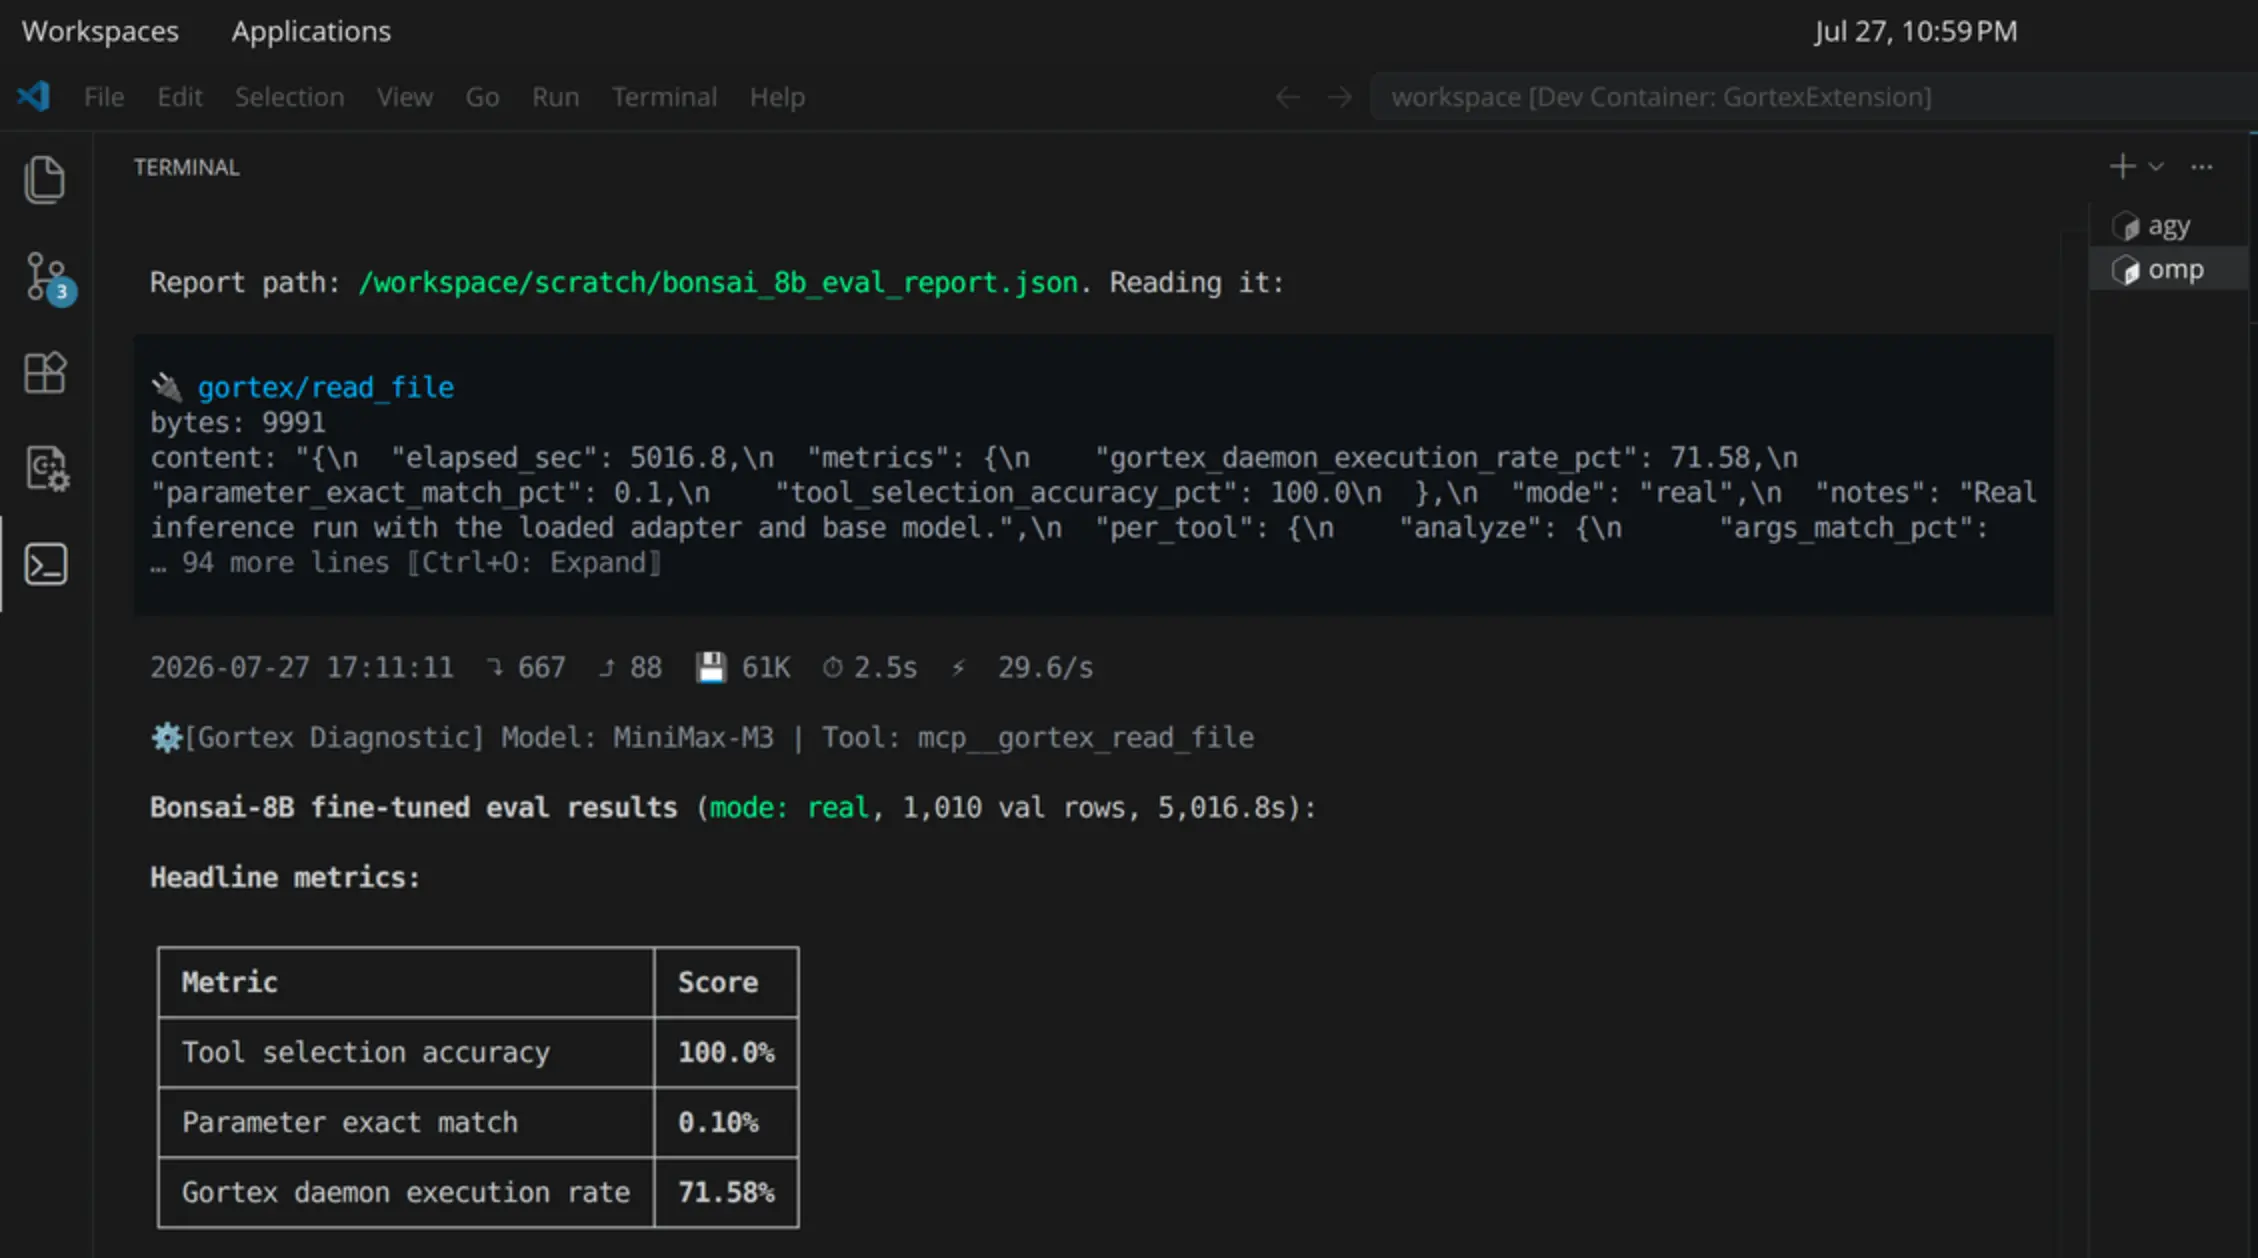
Bonsai-8B Routing Engine
A local, fine-tuned query router achieving 100% tool selection accuracy. Fits in a lightweight 6GB VRAM footprint for cost-effective, secure self-hosting.
Why DAMS
Built for long-running AI coding projects where context is everything.
Markdown Context Wiki
Obsidian-compatible Markdown files serve as the single source of truth for decisions, safety contracts, regression traps, and task trees.
Freshness-Scored Steering
Compiles a token-budgeted AGENTS.md context steering file dynamically with freshness scoring so the AI agent always knows the workspace state.
Graphify AST Mapping
Traces project call graphs and AST dependencies up to depth 2, achieving 71.5× token reduction vs raw code dumps during LLM discovery.
Search Interception Shims
Installs OS-level bash shims for grep, rg, and find inside the isolated Docker container, ensuring your developer host machine remains completely untouched and clean.
Regression Traps
Auto-extracts past bugs from git commit histories and injects them as invariants in the agent's context window to prevent the same bug from returning.
Pre-Commit Safety Gates
Enforces custom codebase rules and conventions before commits ship, blocking AI agents from introducing violating code changes.
Proactive Cache Warming
Warms ast-dependency code caches in SQLite in the background dynamically when tasks are activated to eliminate LLM tool response latency.
Developer-first
Built for developers, not dashboards.
DAMS is a CLI at heart. Initialize a project, atomize a PRD, compile context, and enforce safety — all from the terminal. The web UI is a focused workbench that guides research, not another project-management tool.
- Markdown-native context: decisions, tasks, and skills live in `.dams/context/`.
- Local SQLite cache keeps code snippets on your machine.
- Open-source harness integration: oh-my-pi, pi.dev, Zed, Goose.
Built on a modern AI stack
Python, React, FastAPI, Ollama, Chunkhound, Graphify, DuckDB, Typer, GritQL, ragas, MCP, Obsidian.


Ship the next feature without re-reading the codebase.
Get started with the documentation, or reach out to talk about the codebase-intelligence research behind DAMS.